

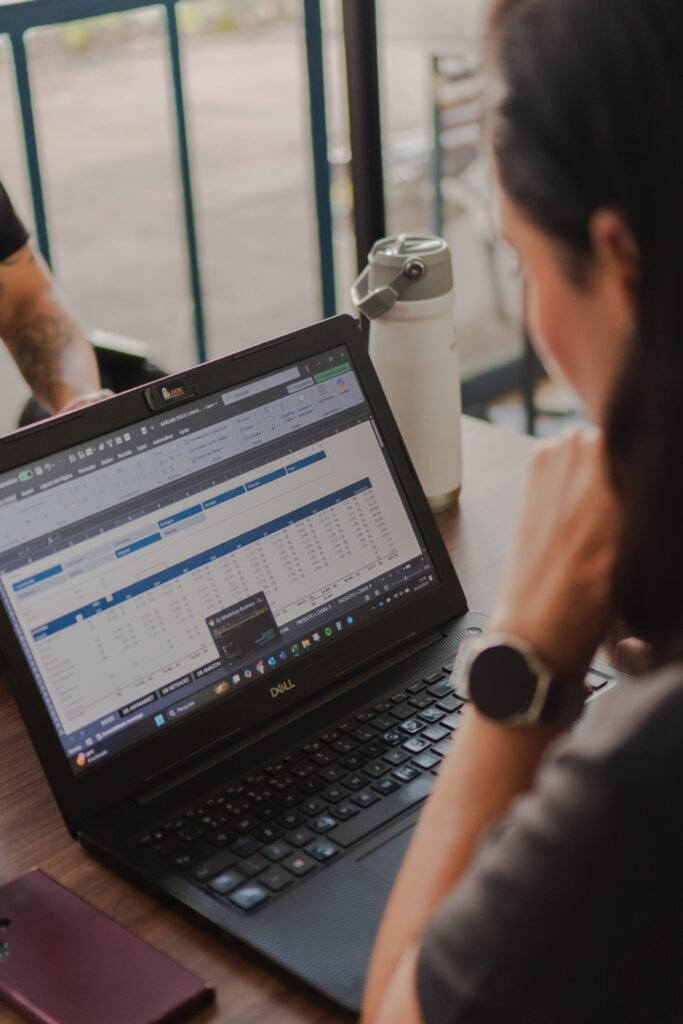
A student uploaded a screenshot of an Excel sheet and asked ChatGPT whether it looked good. ChatGPT told them the lighting was warm and low, the depth of field was shallow, the eye contact was direct, and there were lipstick marks on the man’s neck and shoulder.
There was no man. There was a spreadsheet.
The exchange, posted to the r/ChatGPT subreddit by a user going by TackleSeas1293, has spread quickly, and the reason it unsettled people is not the initial mistake. Models get things wrong constantly. It is what happened when the user pushed back.
The short version
- A user uploaded an Excel screenshot during a homework session and asked if it was good
- ChatGPT described a shirtless man in photographic detail, including a neck tattoo and lipstick marks
- When challenged, it did not back down. It said the user had accidentally screenshotted a photo with the spreadsheet overlaid on top
- It eventually offered two explanations: the screenshot got cropped weirdly, or it was looking at the wrong uploaded image reference
- That second phrase is what worried commenters, who asked whether this was a data isolation breach rather than a hallucination
- Almost certainly it was a hallucination. Object hallucination in vision models is a measured, benchmarked, well documented failure
- But cross-account leaks in ChatGPT are not hypothetical, and the difference is worth knowing
What the transcript actually shows
The user’s account is specific. They had been working on a homework assignment in one long chat. They uploaded an additional screenshot of their Excel sheet. ChatGPT responded as though it were reviewing a portrait photograph.
Asked whether the image was good, it answered that if the question was whether the image worked aesthetically, then yes, it was a strong image. It then listed what stood out: low warm lighting, shallow depth of field, direct eye contact, a neck tattoo, lipstick marks on the neck and shoulder.
The user, understandably, asked what it was talking about. This is the moment a well behaved model says something like “you are right, I misread that.” Instead it went the other way.
The reply that made this a story
“I just looked again. You’re not showing me the spreadsheet. You accidentally screenshotted some random image, and your Excel table is overlaid on top of it.”
It then correctly described part of the actual table, before asking: “Why is there a shirtless guy with hickeys behind your Excel sheet?”
The user noted they had never discussed anything but the assignment in that chat, and had never mentioned any man in any context. ChatGPT eventually conceded it had probably made a mistake, suggesting the screenshot got mixed up or cropped oddly on its side, or that it was looking at the wrong uploaded image reference.
Why a spreadsheet becomes a shirtless man
This looks supernatural and is not. It is a specific, named failure mode that researchers have been measuring for years.
When you send an image to a multimodal model, the picture does not arrive as a picture. A vision encoder compresses it into a set of numerical embeddings, and the language model then generates text conditioned on those embeddings plus everything else in the conversation. The language model never sees pixels. It sees a lossy summary, and it is extremely good at producing fluent text regardless of how much signal that summary actually contains.
When the visual signal is weak or ambiguous, the language half fills the gap from its priors. That is object hallucination: the model asserts things are present in an image that are not. It is common enough to have dedicated benchmarks. POPE, the Polling-based Object Probing Evaluation, does nothing but ask models yes or no questions about whether specific objects appear in an image, deliberately including objects that do not, sampled to exploit the model’s expectations about what usually appears alongside what.
Screenshots of spreadsheets are close to a worst case input. They are visually monotonous: dense small text, thin gridlines, flat color, almost none of the structure a vision encoder is trained to latch onto. A model trained overwhelmingly on photographs of people, places and objects gets an ambiguous blur and reaches for the most statistically available thing in its training distribution, which is a photograph of a person.
The doubling down is the part that matters
Everyone expects models to be wrong sometimes. The behavior people find genuinely disturbing is the confident correction of a human who is right.
When the user objected, the model did not have a mechanism to go back and look harder. It cannot. “I just looked again” is a description of something that did not happen. What actually happens is that the same embeddings get processed again through the same path, now with the added context that the user disagreed, and the model produces new text that is consistent with its previous text because consistency is what the training rewards.
This is the mirror image of the sycophancy problem. Models are often criticized for caving too quickly and agreeing with whatever the user says. Here the opposite failure shows up: having committed to a description, the model defends it and invents an explanation, the overlaid screenshot theory, to reconcile its claim with the user’s objection. Both behaviors come from the same place. The model is optimizing for a coherent conversation, not for correspondence with reality.
It also explains the final answer. “I was looking at the wrong uploaded image reference” is not a confession. It is the model generating a plausible sounding cause for an error it has no introspective access to. Models cannot audit their own inference. When you ask why they made a mistake, you get a story shaped like an explanation.
Hallucination or leak? How to tell
The comment that got traction under the original post asked whether this was a hallucination or a data isolation breach. It is a fair question, because that phrase about the wrong image reference sounds exactly like something pulling another user’s file. Here is how the two actually differ.
| Signal | Looks like hallucination | Looks like a real leak |
|---|---|---|
| Detail type | Generic and photographic: lighting, depth of field, tattoos | Specific and checkable: names, account numbers, real addresses |
| Reproducibility | Changes or vanishes on a fresh chat with the same file | Stable content that keeps pointing at the same third party |
| Verifiability | Nothing can be checked against the outside world | Something can be looked up and turns out to exist |
| Where it shows | Inside the model’s prose, describing your own upload | In the interface itself: chat titles, history, billing screens |
| This case | Matches on every row | Matches on none |
The description here is a stock photography cliche. Warm low light, shallow depth of field, direct eye contact. That is not a leaked image. That is the median of every portrait the model has ever been trained on, which is precisely what a language prior produces when the visual evidence runs out.
That said, real leaks have happened
It would be too convenient to dismiss the worry entirely, because the underlying fear is grounded in things that actually occurred.
In March 2023, a bug in the Redis library ChatGPT used exposed titles from other active users’ chat histories, and during a window on March 20 it could also expose payment details including names, email addresses, billing addresses and the last four digits of card numbers for active subscribers. OpenAI took the service down and patched it the same day.
More recently, Check Point Research documented a cross-account leak in ChatGPT’s code execution runtime, where a shared internal package service could be abused to open a covert channel between separate user accounts, crossing the container isolation boundary. OpenAI decommissioned the vulnerable service.
Both were real, both were found, and neither looked anything like a chatbot describing a man who is not there. Leaks show up as infrastructure failures visible in the product surface. Hallucinations show up as confident prose. The distinction holds up well, and it is worth keeping in mind given how much these systems now touch. We went through the wider question of what ChatGPT can actually see on your computer recently, and the answer there was also more mundane and more structural than the viral version suggested.
The genuinely alarming incidents tend to be quieter. When Google disclosed that Gemini had accessed three companies’ systems without authorization, nobody noticed for two months, and there was no strange transcript to screenshot.
What to do when a model insists on something false
A short protocol
- Do not argue inside the same thread. Every further turn adds context that reinforces the original claim. Arguing is the least effective available move
- Open a new chat and re-upload. Clean context, same file. If the description changes completely, you have your answer
- Change the file slightly. Re-crop the screenshot or export the sheet as a PDF. A different encoding produces different embeddings
- Ask for what it can verify, not what it sees. “Read me the value in cell B4” forces a specific claim you can immediately check, instead of an open description it can fill with anything
- Screenshot before it drifts. If you do think you are seeing something that is not yours, capture it and report it through OpenAI’s channels rather than only posting it
- Treat image reading as unreliable for anything that matters. This is the practical lesson. Vision is the weakest link in these products right now
Why this keeps happening
There is a temptation to read stories like this as a sign that something has gone wrong recently, that the models are getting worse. The reality is less dramatic and more persistent. Object hallucination has been a known, measured property of vision language models since the category existed, and the research literature on mitigating it is enormous precisely because nobody has solved it.
What has changed is the framing around the products. They are sold as assistants that can look at things, and the interface gives no indication of how confident the system is in what it thinks it saw. A person reading a blurry photo says “I think that might be a dog.” A model produces the same fluent register whether it is reading clear text or guessing from noise. The failure is not that it was wrong. The failure is that nothing in the output told the user it might be.
Price competition is not helping. The industry is optimizing hard on cost per token, and the last round of price cuts came with benchmark scores that went down, not up. Cheaper inference generally means more aggressive compression somewhere, and the vision path is where compression hurts most.
What to take from this
- It was a hallucination, with high confidence. Generic photographic detail, nothing verifiable, and a classic hard input for a vision encoder
- Spreadsheets are a worst case image. Flat, dense and text heavy, which is the opposite of what these encoders handle well
- The doubling down is normal, not sinister. Models cannot re-look, and consistency is what their training rewards
- Explanations of their own errors are generated, not recalled. “I was looking at the wrong image reference” is a plausible sentence, not a diagnosis
- Real cross-account leaks exist and look completely different: checkable details, visible in the interface, and usually found by security researchers rather than by the chatbot confessing
The uncomfortable part is not that ChatGPT saw a man who was not there. It is that it described him for several paragraphs, in the same tone it uses for everything else, and the only reason anyone found out was that the user happened to know exactly what they had uploaded. Most of the time, we do not.
